Unit Testing AI Agents with Pytest
Test a small tool-using AI agent without calling an LLM. Use pytest fixtures and mocks to check tool calls, answers, failures, and provider adapters.
Article summary
TL;DR
- Run the real agent with controlled model decisions and search results for fast, deterministic tests without provider token costs.
- Check tool arguments, results passed between steps, and returned answers without freezing prompt wording.
- Test failures and call limits directly, including the work that must not happen after an error.
- Keep SDK translation in separate adapter tests and use evaluations to assess real model output.
Code for this article
Open the repository to follow along.
artem-istranin/istranin-dev-code-examples01 / WHAT TO TEST
Unit testing AI agents without calling an LLM
A documentation agent receives a question, asks a model what to do, and searches the docs when it needs more information. The code around that model still has ordinary responsibilities: call the right tool, pass its result back, return an answer, and stop when something fails.
Calling a real LLM in every test makes those checks slower and harder to repeat. Answers can vary, requests consume tokens, and a provider outage can fail a test even when your code hasn’t changed.
We’ll build tests around a small agent with one search tool. Pytest will run the real application logic while mocks supply model decisions and search results. That gives us fast, deterministic tests with no provider token costs or API keys. We’ll also test the model adapters separately, keeping the SDK real and replacing its HTTP connection.
What should unit tests for AI agents check?
Unit tests should check the application’s response to known model decisions: tool selection and arguments, data passed between steps, returned results, and failure handling. Supply those decisions in the test so the outcome doesn’t depend on a live model.
Two places to replace external behavior

At A, we test the agent with a mocked model and search tool. At B, we test the provider adapter with the real SDK and local HTTP responses. The same architecture supports both; each test keeps the component it is checking real.
You should be comfortable with basic Python and pytest. The pytest mocking tutorial explains the mock assertions used below.
02 / RUN THE EXAMPLE
Start with the working example
The full example package contains the agent, OpenAI and Anthropic adapters, and both test layers. You need Python 3.13 or later and uv.
git clone --depth 1 https://github.com/artem-istranin/istranin-dev-code-examples.git
cd istranin-dev-code-examples/pytest-llm-fixtures
uv sync --locked
uv run pytest -v
uv sync --locked installs the versions recorded in the lockfile. uv run pytest -v runs the tests in that environment with more detailed output. Expect 38 passing tests. Package installation needs network access; the tests run without contacting an LLM or search service.
This walkthrough explains the finished files. The snippets are already there, so don’t paste duplicate tests into them.
| File | Responsibility |
|---|---|
agent.py |
Model contract, decisions, and the agent loop |
providers.py |
SDK requests, response validation, and provider errors |
tests/unit/ |
Agent tests with controlled model and tool behavior |
tests/adapters/ |
Adapter tests with local HTTP responses |
Keep the lockfile for this walkthrough. The verified environment uses Python 3.13.12, pytest 9.1.1, OpenAI 3.24.0, and Anthropic 1.11.0. The installed SDKs use httpx2, which matters when we configure the HTTP mock later.
03 / THE AGENT CONTRACT
Give the agent a small model interface
Our agent answers questions about project documentation. For “Which Python version do I need?”, a model might request a search for “installation requirements”. The agent runs that search, gives the result to the model, and returns its next answer.
The model adapter exposes a decide() method. It receives the user’s question and previous search results, then returns a Decision with 2 fields:
Decision(action="search_docs", value="installation requirements")
Decision(action="answer", value="Use Python 3.13 or newer.")
search_docs means “call the search tool with this query”; answer means “return this text”. The application defines this format. It isn’t OpenAI or Anthropic’s native tool-calling protocol.
An Observation holds a completed search:
@dataclass(frozen=True)
class Observation:

    query: str
    result: str
The model contract uses those values:
class DecisionModel(Protocol):

    def decide(
        self, *, question: str, observations: tuple[Observation, ...]
    ) -> Decision:
        ...
Protocol describes the interface an object must provide. A real provider adapter and a test mock can both satisfy it. The tuple carries the results collected so far; it starts empty for each question.
This keeps provider response objects and prompt formatting outside the agent. The adapter owns that translation. A test can work with a query and result directly instead of inspecting a formatted prompt.
Practice fixtures and mocking in the Pytest course, then use them to describe your agent’s behavior.
View courseHere is the complete loop from agent.py:
def run_agent(
    model: DecisionModel,
    search_docs: Callable[[str], str],
    question: str,
    *,
    max_steps: int = 3,
) -> str:
    if max_steps < 1:
        raise ValueError("max_steps must be positive")
    observations: tuple[Observation, ...] = ()
    for step in range(max_steps):
        decision = model.decide(question=question, observations=observations)
        if decision.action == "answer":
            return decision.value
        if step < max_steps - 1:
            result = search_docs(decision.value)
            observations += (Observation(query=decision.value, result=result),)
    raise StepLimitExceeded("No answer within the model-call budget")
The search function is another dependency passed by the caller. It accepts a query and returns result text. In an application it could wrap a documentation index or web search API; here, the tests supply its behavior.
Each turn either returns an answer or performs a search. Search results accumulate in a new tuple for the next turn. max_steps limits model calls, and the final allowed turn cannot trigger another search because no model call remains to use it.
04 / A: TEST THE AGENT
Replace the model and search tool with predictable results

At A, the agent is the code under test. Neither the provider SDK nor the real search implementation needs to run.
The model_script fixture in tests/unit/conftest.py lets each test choose what the model returns:
@pytest.fixture
def model_script(mocker):

    def make(*outcomes):
        model = mocker.create_autospec(DecisionModel, instance=True, spec_set=True)
        model.decide.side_effect = outcomes
        return model

    return make
mocker comes from pytest-mock. create_autospec creates a mock with the DecisionModel interface and checks method arguments. spec_set=True also rejects unknown attributes. These checks don’t validate returned values, so the tests supply real Decision objects.
side_effect consumes the supplied outcomes in order. Each call returns the next decision, or raises the next exception. If the agent makes an unexpected extra call, the sequence runs out and the test fails. See the Python mock documentation for the supported forms of side_effect.
The second fixture supplies a search mock:
@pytest.fixture
def search_tool(mocker):

    def search_docs(query: str) -> str:
        raise NotImplementedError

    return mocker.create_autospec(search_docs, spec_set=True)
The nested function defines the expected signature; its body never runs. create_autospec replaces it with a callable mock. Each test sets its return value or exception.
Both fixtures use pytest’s default function scope, giving each test fresh call history and outcomes. The fixture and parametrization guide explains this factory pattern in more detail.
Start with an answer that needs no search
In tests/unit/test_agent.py, the simplest case supplies one answer:
def test_direct_answer_does_not_search(model_script, search_tool):
    model = model_script(Decision(action="answer", value="Hello!"))

    result = run_agent(model, search_tool, "Hello")

    assert result == "Hello!"
    model.decide.assert_called_once_with(question="Hello", observations=())
    search_tool.assert_not_called()
This checks 3 application promises: the caller receives the answer, the model receives the question with no previous results, and the search tool stays unused. The greeting is just a fixed test value. We aren’t judging the quality of a generated answer.
Add a search before the answer
Now script 2 decisions and one search result:
def test_search_then_answer(model_script, search_tool, mocker):
    model = model_script(
        Decision(action="search_docs", value="installation requirements"),
        Decision(action="answer", value="Use Python 3.13 or newer."),
    )
    search_tool.return_value = "Requires Python >=3.13."
    question = "Which Python version do I need?"

    result = run_agent(model, search_tool, question)

    assert result == "Use Python 3.13 or newer."
    search_tool.assert_called_once_with("installation requirements")
    assert model.decide.call_args_list == [
        mocker.call(question=question, observations=()),
        mocker.call(
            question=question,
            observations=(
                Observation("installation requirements", "Requires Python >=3.13."),
            ),
        ),
    ]
The test reads like the interaction we expect. The first model call receives the question. Its search decision leads to exactly one tool call with the requested query. The next model call receives an Observation containing that query and the tool’s result. Finally, the agent returns the answer.
Comparing call_args_list checks those 2 calls in order, including their arguments. mocker.call is a convenient way to describe an expected call. These assertions concern data exchanged between components, so changing the adapter’s prompt wording doesn’t break them.
Run the agent tests:
uv run --locked pytest tests/unit -v
All 7 cases pass. The same chosen decisions exercise the same application paths on every run; no model has to generate them.
05 / FAILURES AND LIMITS
Test failures without waiting for a provider outage
Controlled dependencies let us trigger failure paths immediately. This agent’s policy is to propagate errors and stop; it does not retry or invent a fallback answer.
For a model failure, put an exception in the script:
def test_model_failure_stops_without_retry(model_script, search_tool):
    model = model_script(ModelUnavailable("busy"))

    with pytest.raises(ModelUnavailable):
        run_agent(model, search_tool, "Which Python version?")

    assert model.decide.call_count == 1
    search_tool.assert_not_called()
pytest.raises checks the exception visible to the caller. The call count confirms there was no retry, and the unused search mock confirms the failure caused no tool work.
For a search failure, the existing test sets search_tool.side_effect = TimeoutError("search unavailable") after scripting a search decision. It expects the timeout to propagate and checks that the model was called only once. The agent must not continue as though it received a search result.
Stop a model that keeps requesting searches
A model might keep asking for more information. Test that case with repeated decisions, without running a model repeatedly:
def test_budget_stops_before_another_tool_call(model_script, search_tool):
    search = Decision(action="search_docs", value="installation requirements")
    model = model_script(search, search)
    search_tool.return_value = "No matching document."

    with pytest.raises(StepLimitExceeded):
        run_agent(model, search_tool, "Which Python version?", max_steps=2)

    assert model.decide.call_count == 2
    search_tool.assert_called_once_with("installation requirements")
A budget of 2 permits 2 model calls and at most 1 intervening search. The second search decision raises StepLimitExceeded. Both call assertions matter because the limit covers model turns and prevents a search whose result cannot be consumed.
The remaining unit cases reject a nonpositive budget before doing any work and confirm that a second question starts with no previous search results. That last test invokes the agent twice with the same dependencies, so it checks isolation between requests as well as between tests.
These are the example’s policies. If your app retries, falls back to another model, or turns errors into user-facing responses, test that behavior explicitly. Keep retry counts bounded. A model-call limit alone doesn’t impose a total time limit or an exact token budget.
06 / B: TEST THE ADAPTER
Keep the SDK real and replace provider HTTP
The agent tests cover what happens after the model returns a decision. The adapter has a different responsibility: send application data to the provider and turn its response into that decision.
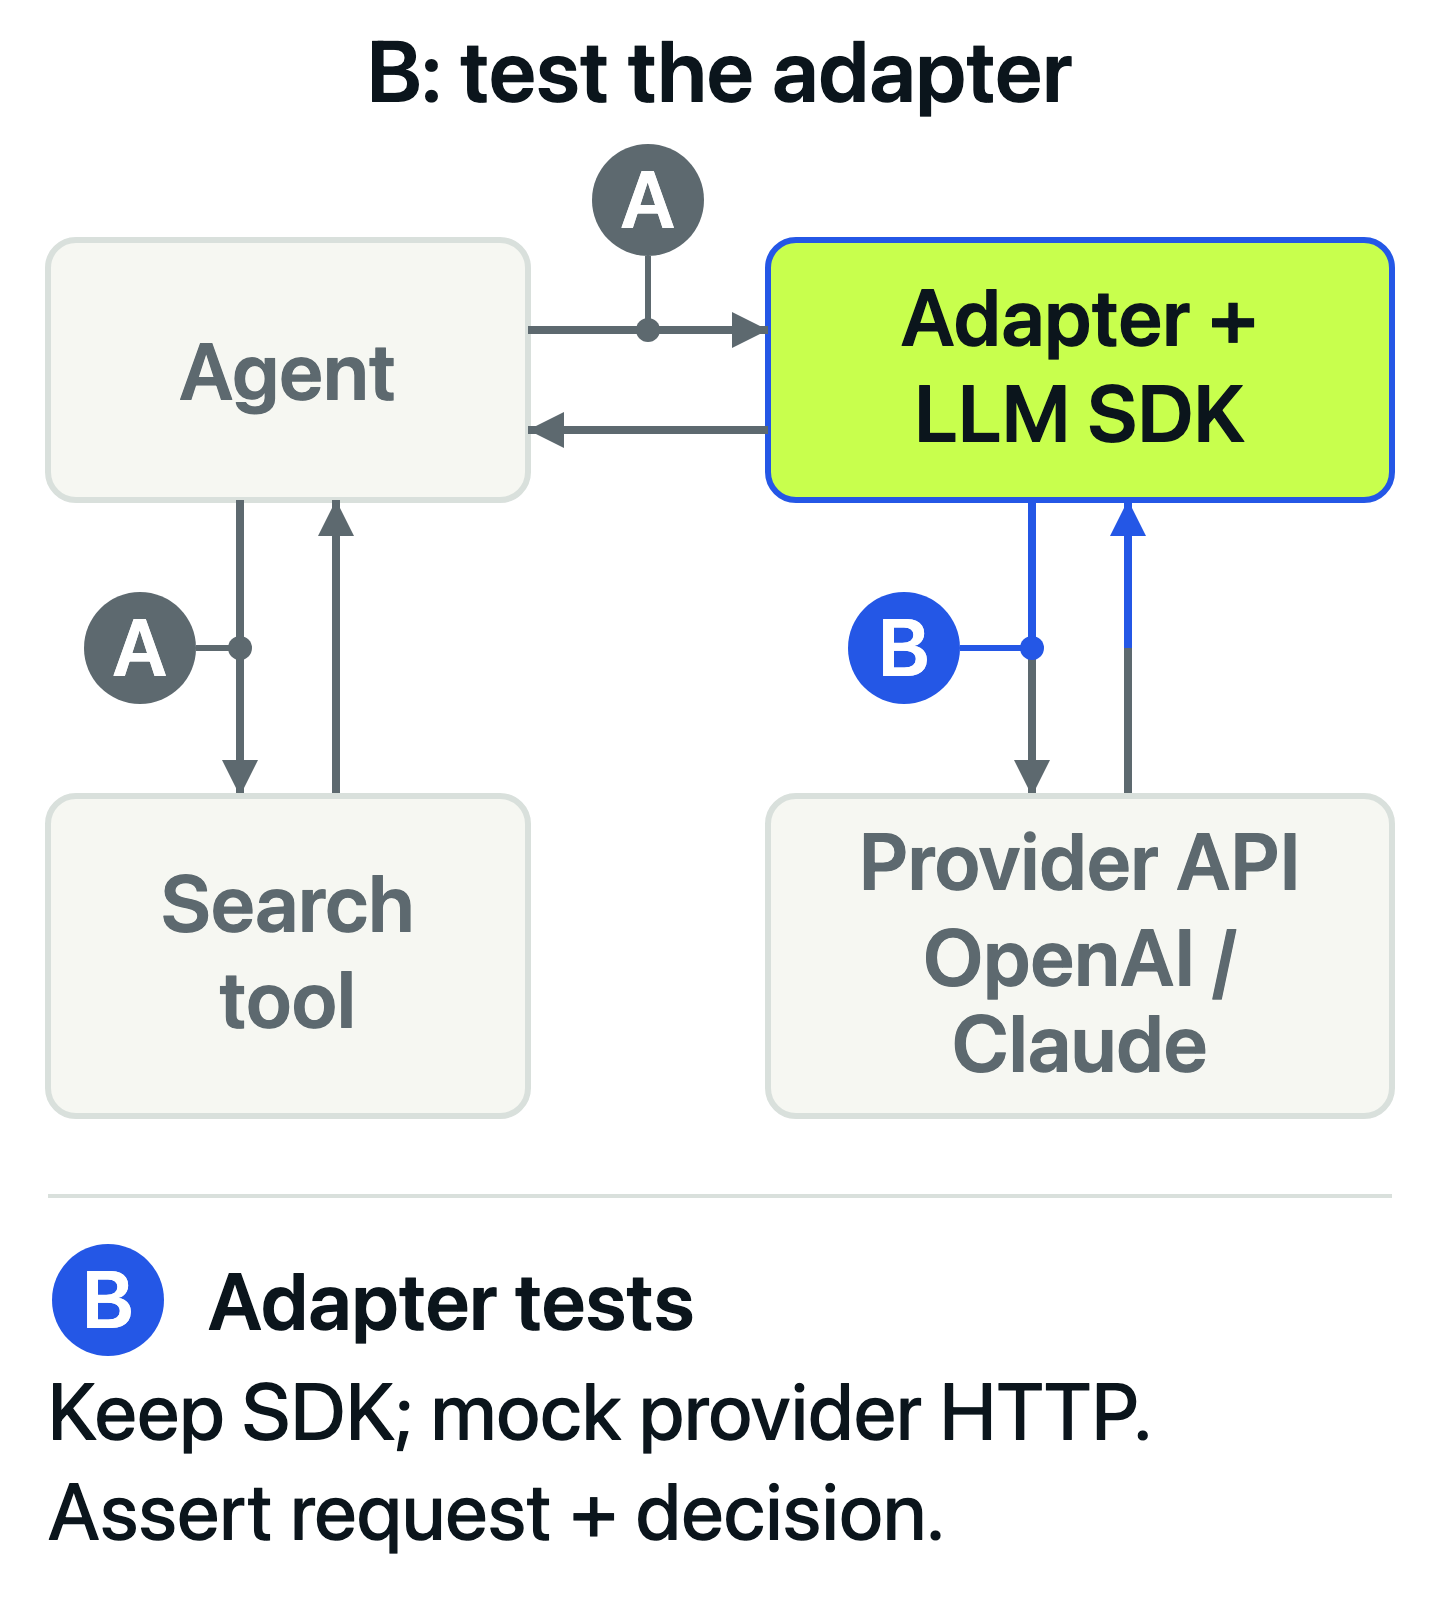
At B, the adapter and installed SDK stay real. A local HTTP transport supplies responses in place of the provider API.
OpenAIModel uses the Responses API. AnthropicModel uses the Messages API. Both expose the same decide() method, validate the returned JSON with the Decision model, and translate timeouts or rate limits into ModelUnavailable.
The response schema lives in agent.py:
class Decision(BaseModel):

    model_config = ConfigDict(extra="forbid", strict=True, frozen=True)
    action: Literal["search_docs", "answer"]
    value: Annotated[str, Field(min_length=1, pattern=r"\S")]
Literal allows only the 2 supported actions. The field requires a string containing at least one non-whitespace character. The configuration rejects extra fields and coercion; frozen=True prevents reassignment after validation. The Pydantic JSON validation documentation explains how model_validate_json() converts provider text into this type.
The adapters require complete responses before parsing them. Invalid JSON or an unsupported action raises InvalidDecision, so no unvalidated model action reaches the agent’s search dispatch.
Replace the connection, not the adapter method
The fixtures in tests/adapters/conftest.py construct a real SDK client using:
http_client = httpx2.Client(
    transport=httpx2.MockTransport(handle), trust_env=False
)
handle receives the outgoing request and returns a prepared httpx2.Response. It records requests for assertions and fails on any request without a configured response. The factory passes this client to the provider SDK and closes it after the test.
This replacement is below decide(), so request construction and response parsing still run. The OpenAI SDK HTTP mocking guide documents the transport approach. Match the transport library to your installed SDK; these locked versions use httpx2.
The provider fixture runs shared tests for OpenAI and Anthropic. response_body wraps supplied text in the appropriate provider response format, while adapter_factory supplies the client and captured requests. This keeps provider-specific envelopes out of the test’s main story.
Check data in both directions
The request-and-response test starts with a synthetic answer and a previous search result:
output = '{"action":"answer","value":"Done"}'
adapter, requests = adapter_factory(
    httpx2.Response(200, json=response_body(output))
)
observation = Observation(
    "installation requirements", "Requires Python >=3.13."
)

decision = adapter.decide(
    question="Which Python version?", observations=(observation,)
)

assert decision == Decision(action="answer", value="Done")
assert len(requests) == 1
The returned value is an application Decision, not an SDK response. The rest of the test decodes the recorded request and checks its method, API path, model identifier, question, and search results. For OpenAI, the application data is in input; for Anthropic, it is in a user message.
We check those fields because they carry the adapter’s contract. There is no assertion that freezes the system prompt’s exact prose. The model identifier and credentials in these tests are dummy values used only by the local transport.
Cover rejected responses and provider errors
The adapter suite exercises these outcomes for both providers:
| Provider outcome | Expected result |
|---|---|
| Completed, valid decision | Return a Decision |
| Malformed JSON, unsupported action, or invalid value | Raise InvalidDecision; don’t call a tool |
| Truncated, empty, or non-text response | Raise InvalidDecision |
| Timeout or HTTP 429 | Raise ModelUnavailable after one request |
| HTTP 401 | Preserve the SDK’s authentication error |
The adapters set max_retries=0 to implement the example’s stop-on-error policy. A synthetic timeout is raised immediately; the test checks error handling rather than waiting for the configured timeout to elapse.
Run this layer separately:
uv run --locked pytest tests/adapters -v
These 30 tests verify the adapters against the installed SDKs and local responses. They don’t establish that a live endpoint accepts your real credentials or model choice. That needs a separate integration check.
07 / OFFLINE CI
Make accidental network access fail
Mocks make the intended calls local. A network guard catches a call you forgot to replace.
The project enables pytest-socket through --disable-socket in pytest’s default options. An autouse fixture also removes provider credentials from the test environment. SDK fixtures receive explicit dummy keys.
If test code tries to open a real Python socket, the suite fails. This is an in-process guard, not an operating-system sandbox; keep subprocess-based tools and live integration checks in separately configured jobs.
Run the same pytest suite in CI, with dependency installation as a setup step. The test job needs no provider secrets.
For workflow setup, caching, and failure reports, see the GitHub Actions pytest guide.
08 / APPLY THE PATTERN
Choose tests by the responsibility they protect
We now have repeatable tests for the agent’s decisions, tool calls, answers, and failures. The adapter tests cover the translation between application data and provider responses. Neither layer spends tokens or waits for generated output.
Do unit tests replace evaluations for AI agents?
No. Unit tests check application behavior for controlled inputs. Evaluations assess the quality of decisions and answers produced by a model, such as whether it chooses a useful search or answers accurately. Keep those checks separate so ordinary code changes can still be tested quickly and deterministically.
Does this approach require a dedicated LLM mocking plugin?
No. This example uses pytest-mock for application dependencies and a local HTTP transport for SDK adapters. A framework’s own fake model can also work if it exposes the contract your application uses.
Start with one behavior in your own application
Choose a tool-using path and supply known model decisions and a tool result. Keep the agent real. Assert the tool’s arguments, the data passed to the next model call, and the result returned to the caller. Then add the failure policy and a work limit.
LangGraph can replace the run_agent() loop by coordinating model calls, tools, and state. You can also wrap a LangGraph workflow behind an application interface, much as DecisionModel hides the model implementation here. A full workflow may need a broader interface because it does more than return one model decision. To apply these testing ideas in LangGraph, continue with LangGraph testing with pytest.
For an async or streaming interface, use an awaitable or event-producing test double that matches that interface; this example covers synchronous, complete responses.
Replace unpredictable dependencies, then test the decisions your application makes with their results.
Build on this example with the Pytest course lessons on fixtures, parametrization, mocking, and maintainable test suites.
View courseMore field notes
Keep reading.
How to Test a LangGraph Agent with pytest
Use pytest fixtures, parametrization, and exception assertions to test a LangGraph agent: direct answers, tool calls, and service failures.
LangGraphpytestPytest Mocking Tutorial: Patch Dependencies Without Hiding Bugs
Test a wallet with a controlled exchange rate, simulate lookup failures, and see how stricter mocks catch calls that real code would reject.
pytestMockingPytest Fixtures and Parametrization Best Practices
Reuse pytest setup without hiding what each test checks. Follow an inventory example through fixtures, parameter tables, failures, and fresh test data.
pytestPython testing